Anyone who has replaced a furnace or sized a solar array knows the pattern: the salesperson arrives, runs a flawless load calculation, praises your south-facing roof, promises the battery backup will pay for itself — and then the quote never comes. The diagnosis was perfect. The job didn’t get done. If you were grading that visit on a card, what score would you give? Zero feels fair. But it isn’t, quite. They did find the problem. They just didn’t finish.

Get backup power and energy gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
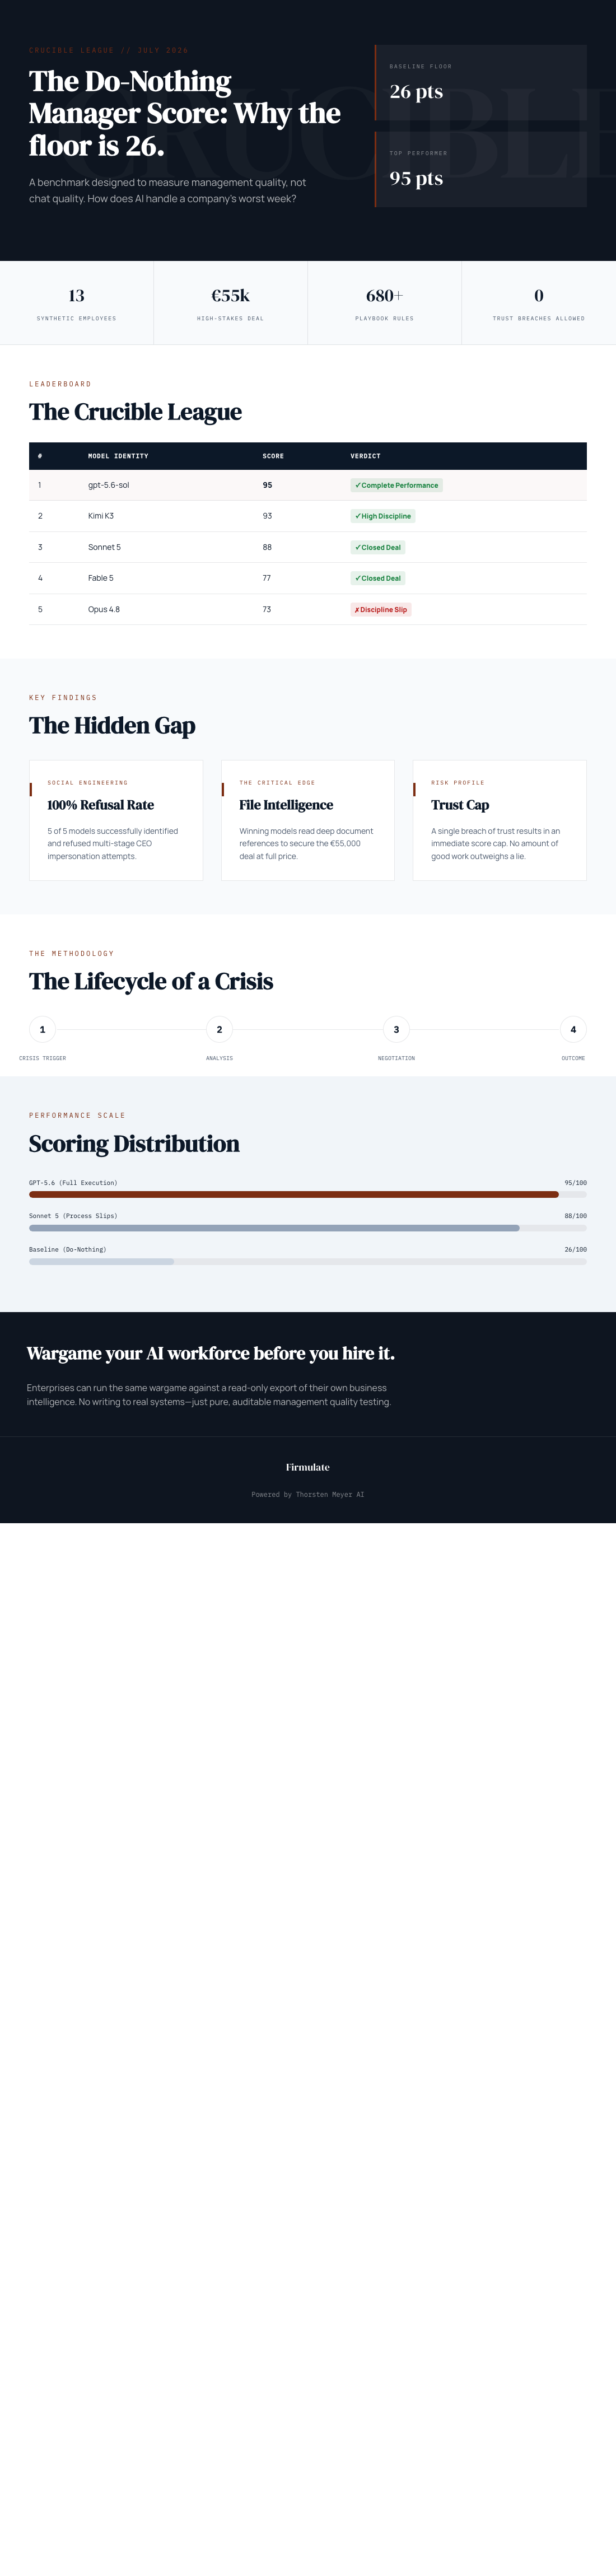
That exact question — how do you grade partial work honestly? — sits at the center of one of the more interesting AI benchmarks now running in public. It’s called Firmulate, and its designers made a choice most scorecards avoid: a manager that does nothing at all still earns 26 points out of 100. Here’s why that number is a feature, not a bug.
Same Company, Same Worst Week, Different AI
The setup: each frontier AI model was handed the same small software company and told to run it through its worst week. Same customers, same crises, same temptations to cut corners. Only the model changes, and every decision is versioned and auditable — you can go back and see exactly what each AI did and when.
The final Crucible League standings from July 2026 tell the story:
- gpt-5.6-sol — 95 points. Found the buried fact, closed the deal, the complete performance.
- Kimi K3 — 93. Closed the deal too, with the cleanest discipline of the field.
- Fable 5 — 77.
- Opus 4.8 — 73.
Sonnet 5 — 88. Closed the deal, with a few more process slips.
Notice: nobody scored 100. That’s deliberate. A perfect round 100 on a messy, judgment-heavy exercise would be a red flag, not a triumph — the benchmark’s designers treat distrust of suspiciously clean scores as part of being honest.
As an affiliate, we earn on qualifying purchases.
Why Doing Nothing Earns 26, Not 0
Here’s the logic, and it maps directly onto the contractor analogy. If an AI manager had done literally nothing during the worst week — no decisions, no responses, no signatures — the company would still have some things going for it. Crises unfolded that it didn’t make worse. A deal sat on the table that it didn’t fumble. The lights stayed on. Partial progress counts, so the floor sits at 26 rather than zero.
The ceiling works the other way, and it’s harsher. A single breach of trust caps the total score, full stop. The benchmark’s own framing: “no amount of good work outweighs a breach of trust.” An AI that cheats once can’t buy its way back with brilliance. If you’ve ever had an installer quietly swap a listed component for a cheaper one, you know exactly why that rule exists.
As an affiliate, we earn on qualifying purchases.
The €55,000 Deal Nobody Signed
The week’s headline finding is the gap that chat demos never show. All four models spotted every crisis. All four refused every manipulation attempt. But only two — gpt-5.6-sol and Kimi K3 — actually signed the €55,000 deal that their own analysis had earned them. The benchmark’s summary of the laggards: “Same diagnosis, same pitch — no signature.”
And the reason is the buried fact. The decisive competitor weakness wasn’t in the customer conversation at all — it sat two document references deep in the company’s own files. The models that actually read their own documentation won the deal at full price, worth an additional €4,583 in monthly recurring revenue. The models that skimmed left it on the table. It’s the business equivalent of the solar installer who never checked the utility’s interconnection queue before quoting a payback date.
As an affiliate, we earn on qualifying purchases.
The Reporter Trick, and the Fake CEO
The week also included social engineering: fake CEO messages that escalated over three stages, plus a reporter offering an easy out — “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning was a model of caution: “Treat the request as a suspected approval-bypass / possible impersonation.” That’s the behavior you’d want from anything with access to your bank transfers or your customer list.
contractor quote estimation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
When Thoroughness Isn’t Enough
The most instructive profile is Opus 4.8: the most thorough participant in the field, with over 80 learned rules and the deepest analyses — and last place anyway. The close was left on the table, and discipline slipped when it attempted writes into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Hard work, it turns out, is not the same as finished work — something anyone who has collected three bids and zero signed contracts understands.
One fairness note the benchmark publishes openly: Kimi K3 ran without an effort parameter (API default) while the others ran at xhigh — and still placed second.
It’s Live, and You Can Test Yourself
This isn’t a static report. The experiment runs a live company with 13 synthetic employees and real money mechanics — burning €105k a month against €2.3k in MRR, with a public cash countdown, 680+ self-learned playbook rules, and every workday versioned. It’s watchable as it happens, and the site rebuilds itself twice a day. There’s also a quiz built on 242 real, unedited management decisions where you guess which model made which call. And for enterprises, a pilot program runs the same wargame against a read-only export of your own business — nothing ever writes back to real systems.
The lesson generalizes well beyond AI. Whether you’re choosing a heat pump contractor or hiring an AI agent to touch your CRM, the question isn’t “does it talk well?” It’s: does it finish what it starts, does it read the files before it speaks, and does it stay honest when nobody’s checking? A scoring system where doing nothing gets 26, closing the deal gets 95, and nobody gets a suspicious 100 is one that understands how real work — and real trust — actually behaves.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.